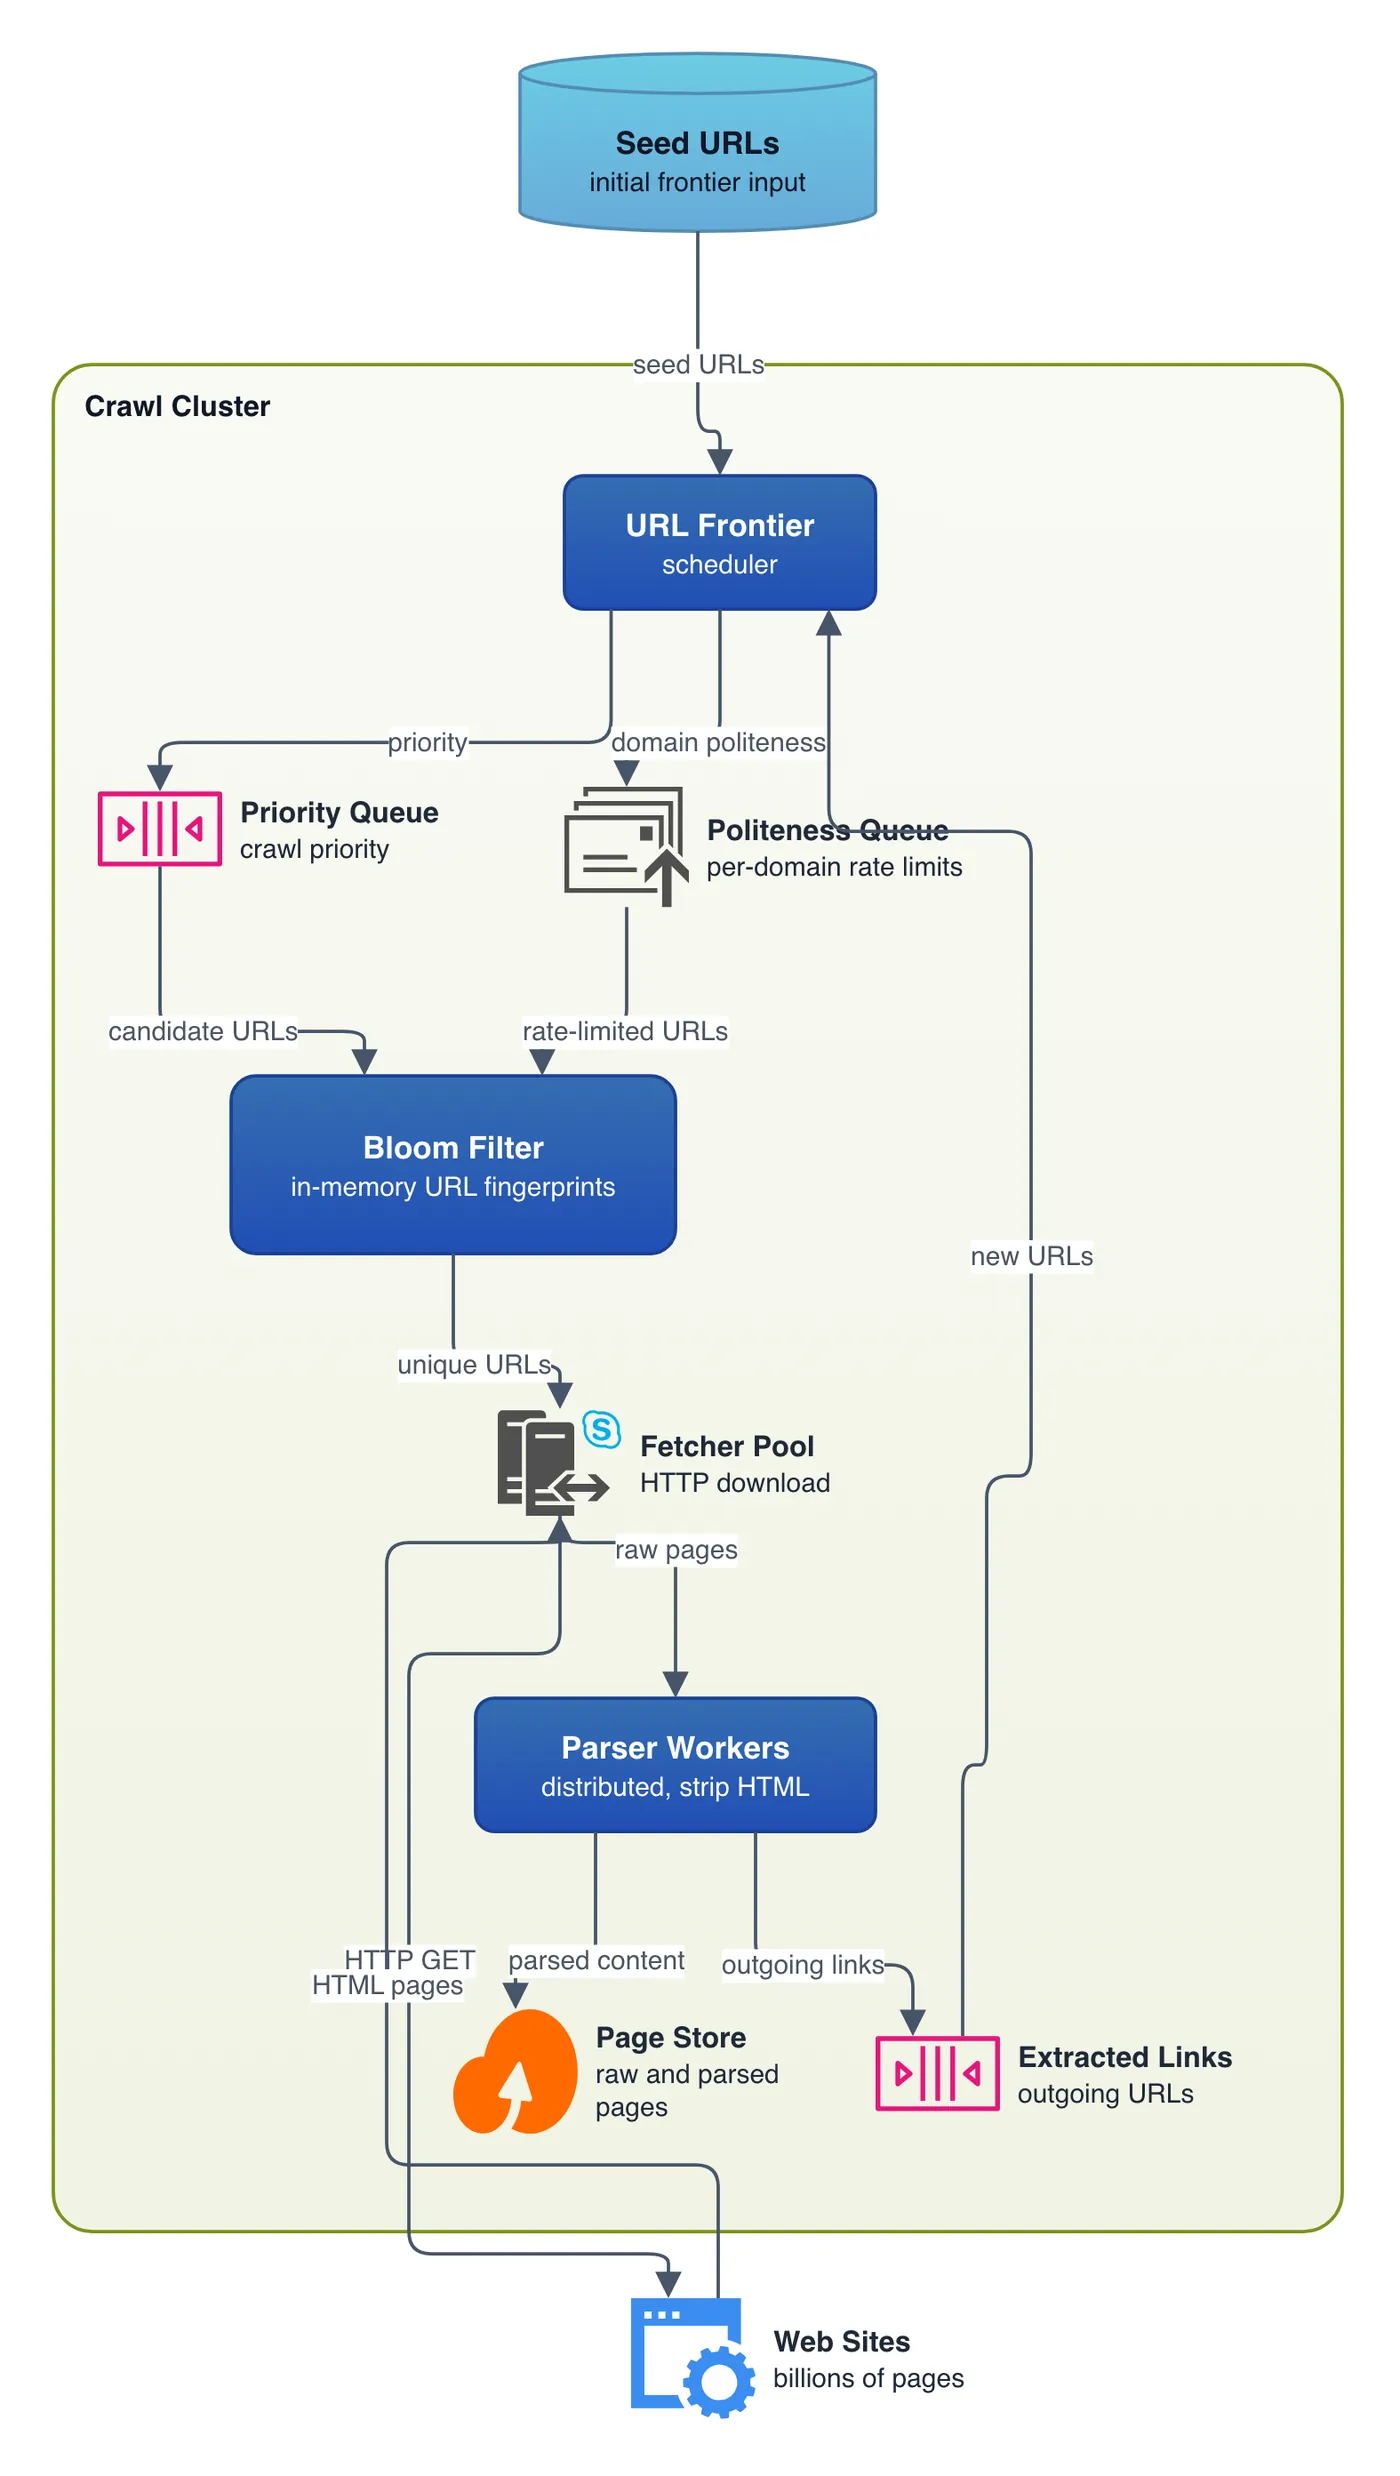
Web Crawler Pipeline: Billion-Page Scale
System Design diagram · made in Skemio
What it shows
- URL Frontiers use dual queues to balance strict politeness with crawling priority.
- Bloom filters detect duplicate URLs in-memory with near-zero memory footprint.
- Distributed parsers strip HTML, extract outgoing links, and feed the frontier.
The takeaway
Politeness-controlled queues and in-memory Bloom filters prevent crawler bans and redundant work.
- #SystemDesign
- #WebCrawler
- #BigData
- #DataEngineering
- #SoftwareArchitecture
- #Algorithms