Accelerating LLMs with Speculative Decoding
Data & AI Pipelines diagram · made in Skemio
What it shows
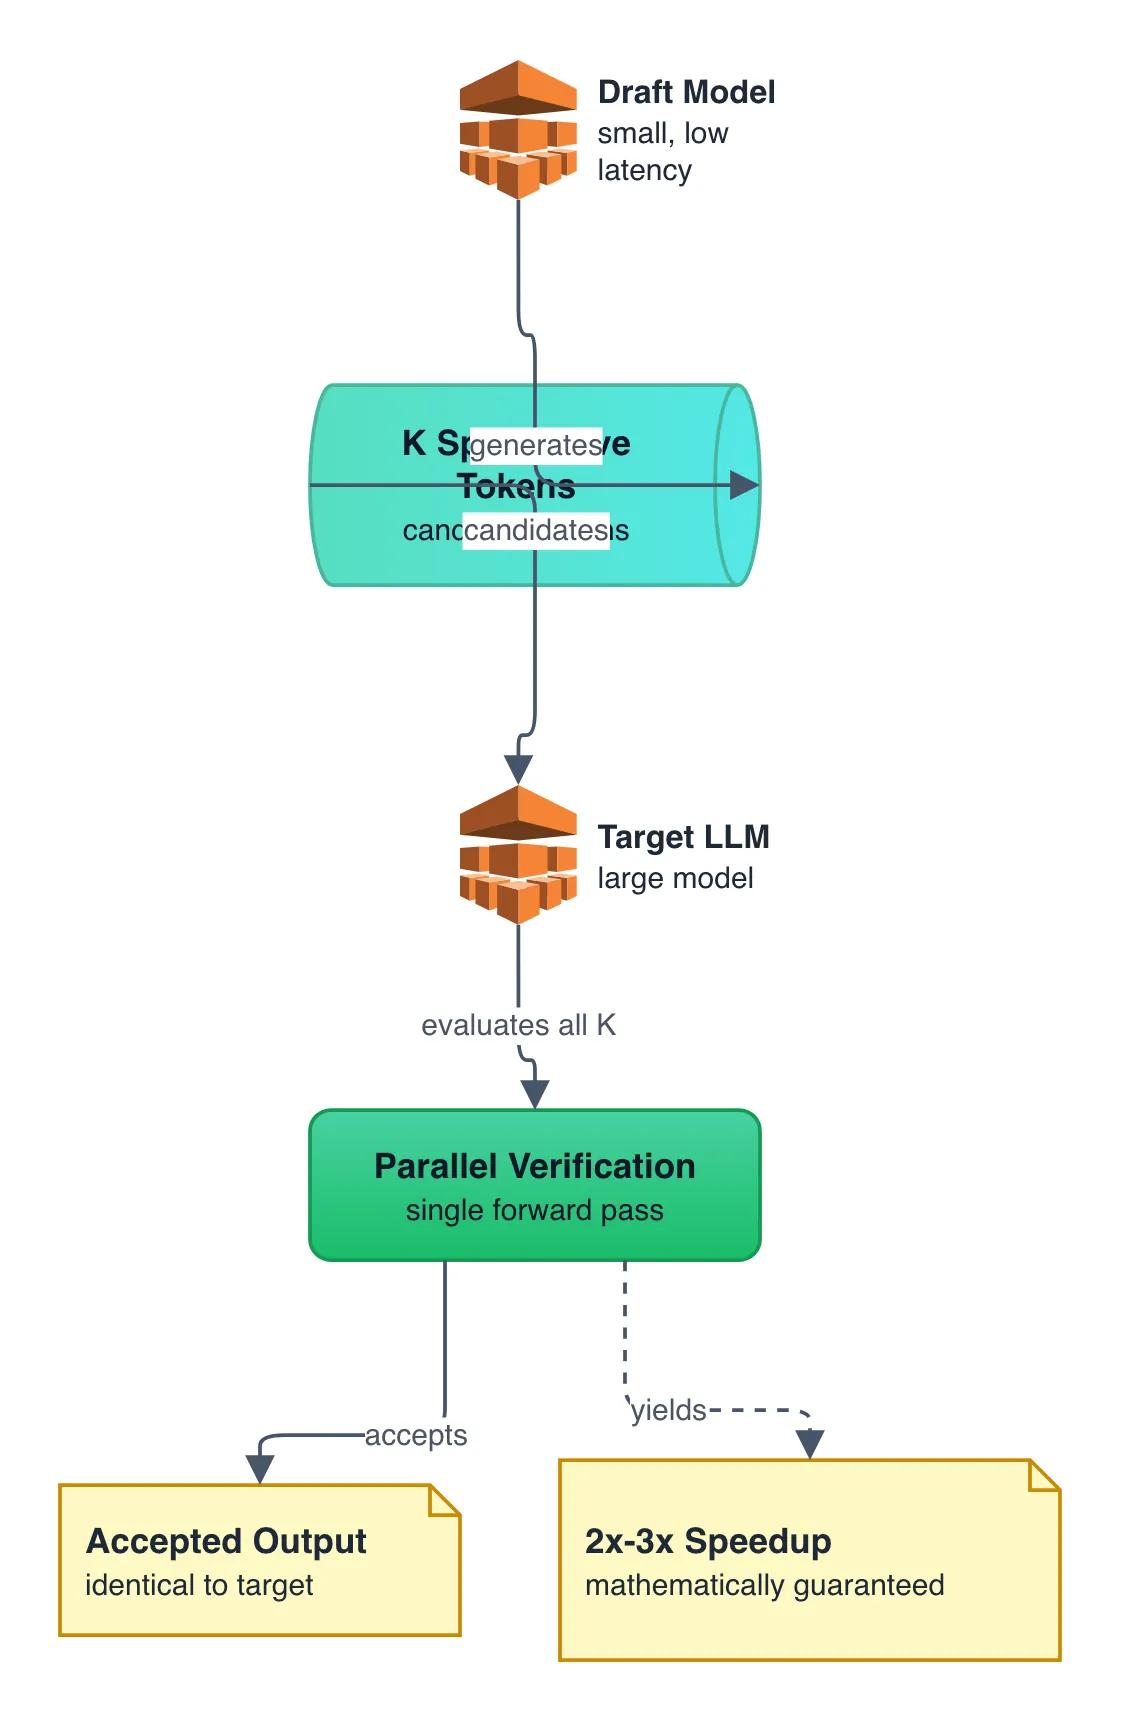
- Small draft model generates K speculative tokens with minimal latency.
- Target LLM evaluates all K candidates in a single parallel forward pass.
- Delivers 2x-3x speedup with mathematical guarantee of identical outputs.
The takeaway
Speculative decoding boosts LLM inference speed up to 3x with zero loss in output quality or accuracy.
- #MachineLearning
- #LLMInference
- #ArtificialIntelligence
- #AIInfrastructure
- #DeepLearning
- #Hardware