Distributed ML Training with FSDP
Data & AI Pipelines diagram · made in Skemio
What it shows
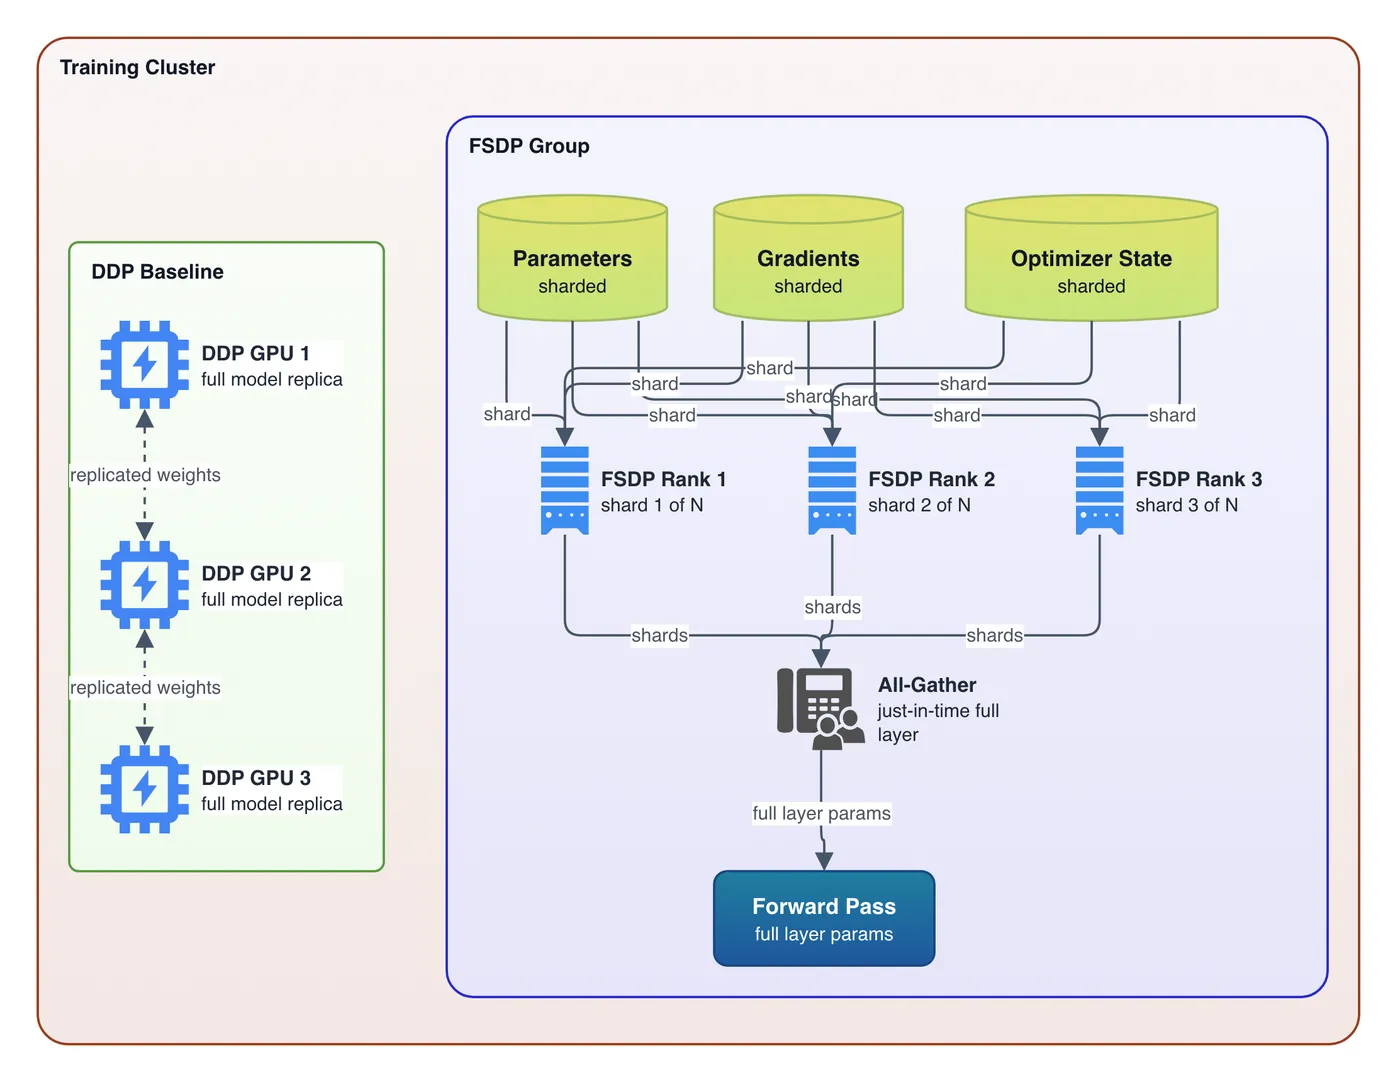
- Standard DDP replicates full model weights on every individual GPU node
- FSDP shards parameters, gradients, and optimizer states across worker ranks
- All-Gather restores full layer parameters just in time for forward passes
The takeaway
FSDP delivers Zero Redundancy Optimizer benefits natively in PyTorch without expensive hardware limits.
- #MachineLearning
- #PyTorch
- #DeepLearning
- #MLOps
- #LLM
- #AI