Fix RAG Recall with Contextual Retrieval
Data & AI Pipelines diagram · made in Skemio
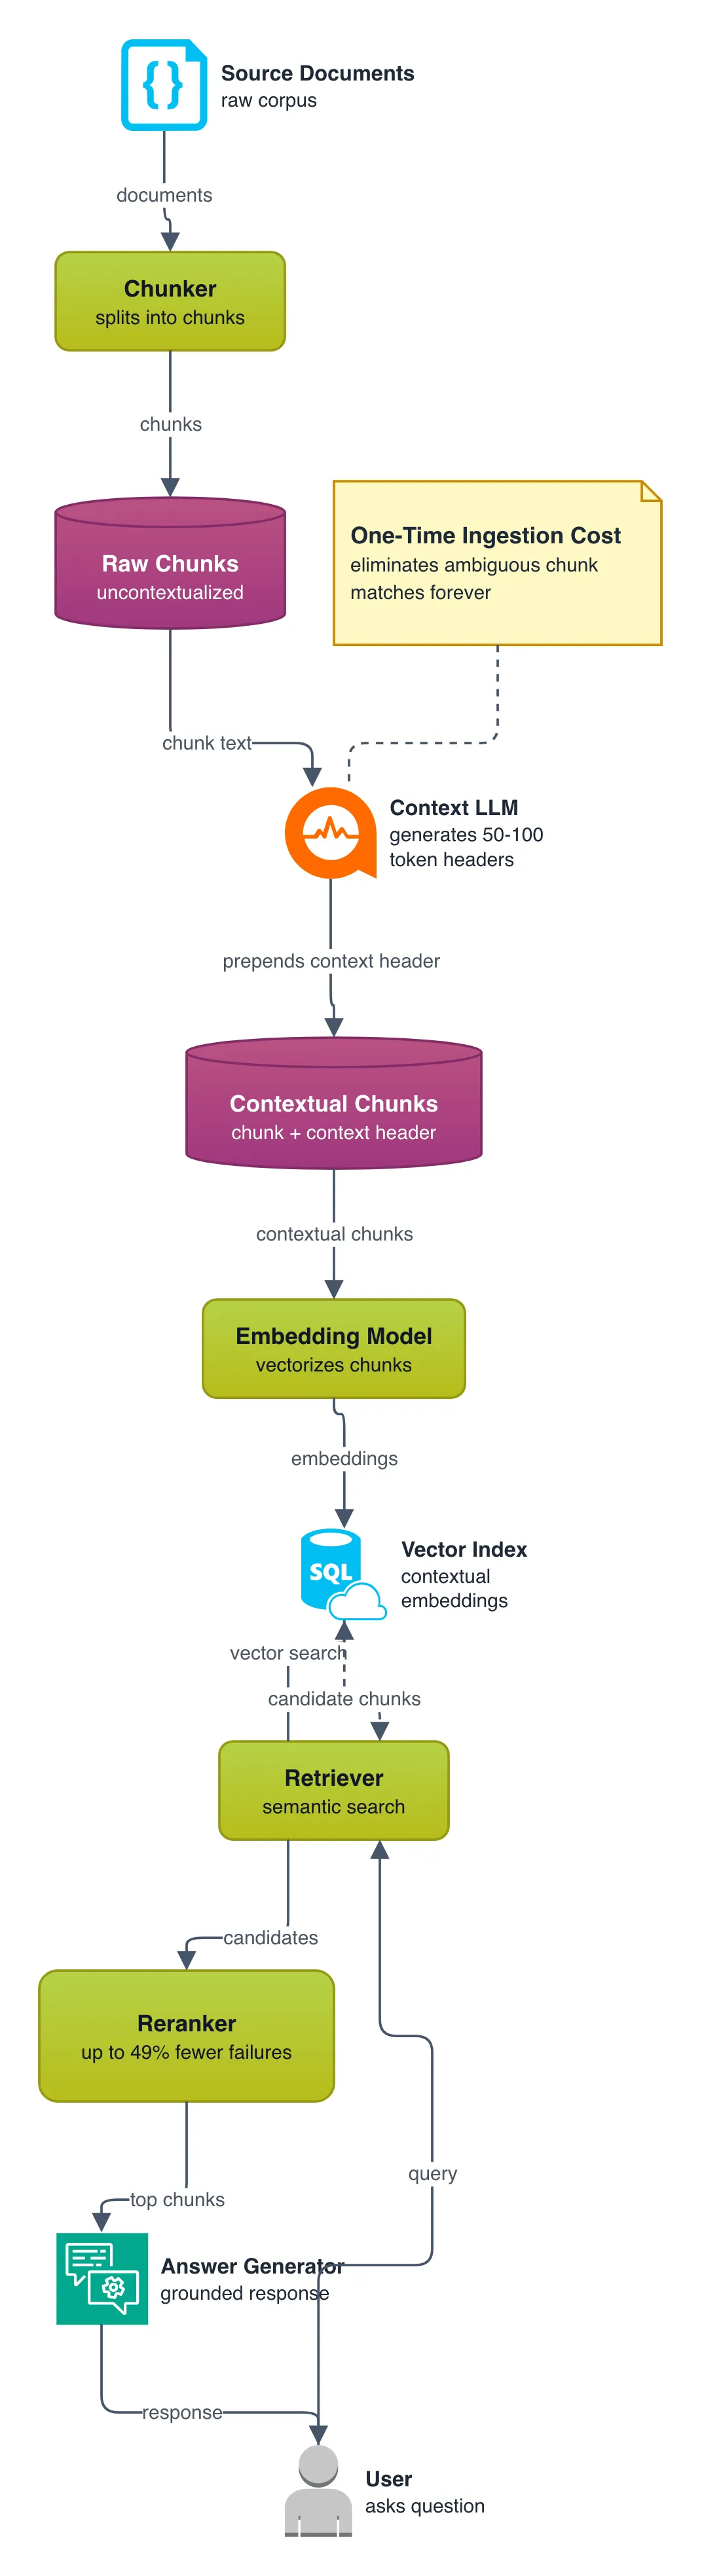
What it shows
- LLMs prepend 50-100 token context headers to each chunk before indexing.
- Reduces retrieval failure rates by up to 49% when paired with reranking.
- One-time ingestion cost eliminates ambiguous chunk matches forever.
The takeaway
Prepend document-level context to chunks before embedding to stop silent RAG failures.
- #RAG
- #LLM
- #VectorDB
- #MachineLearning
- #SystemDesign
- #Search