LLM Semantic Caching with Redis
Data & AI Pipelines diagram · made in Skemio
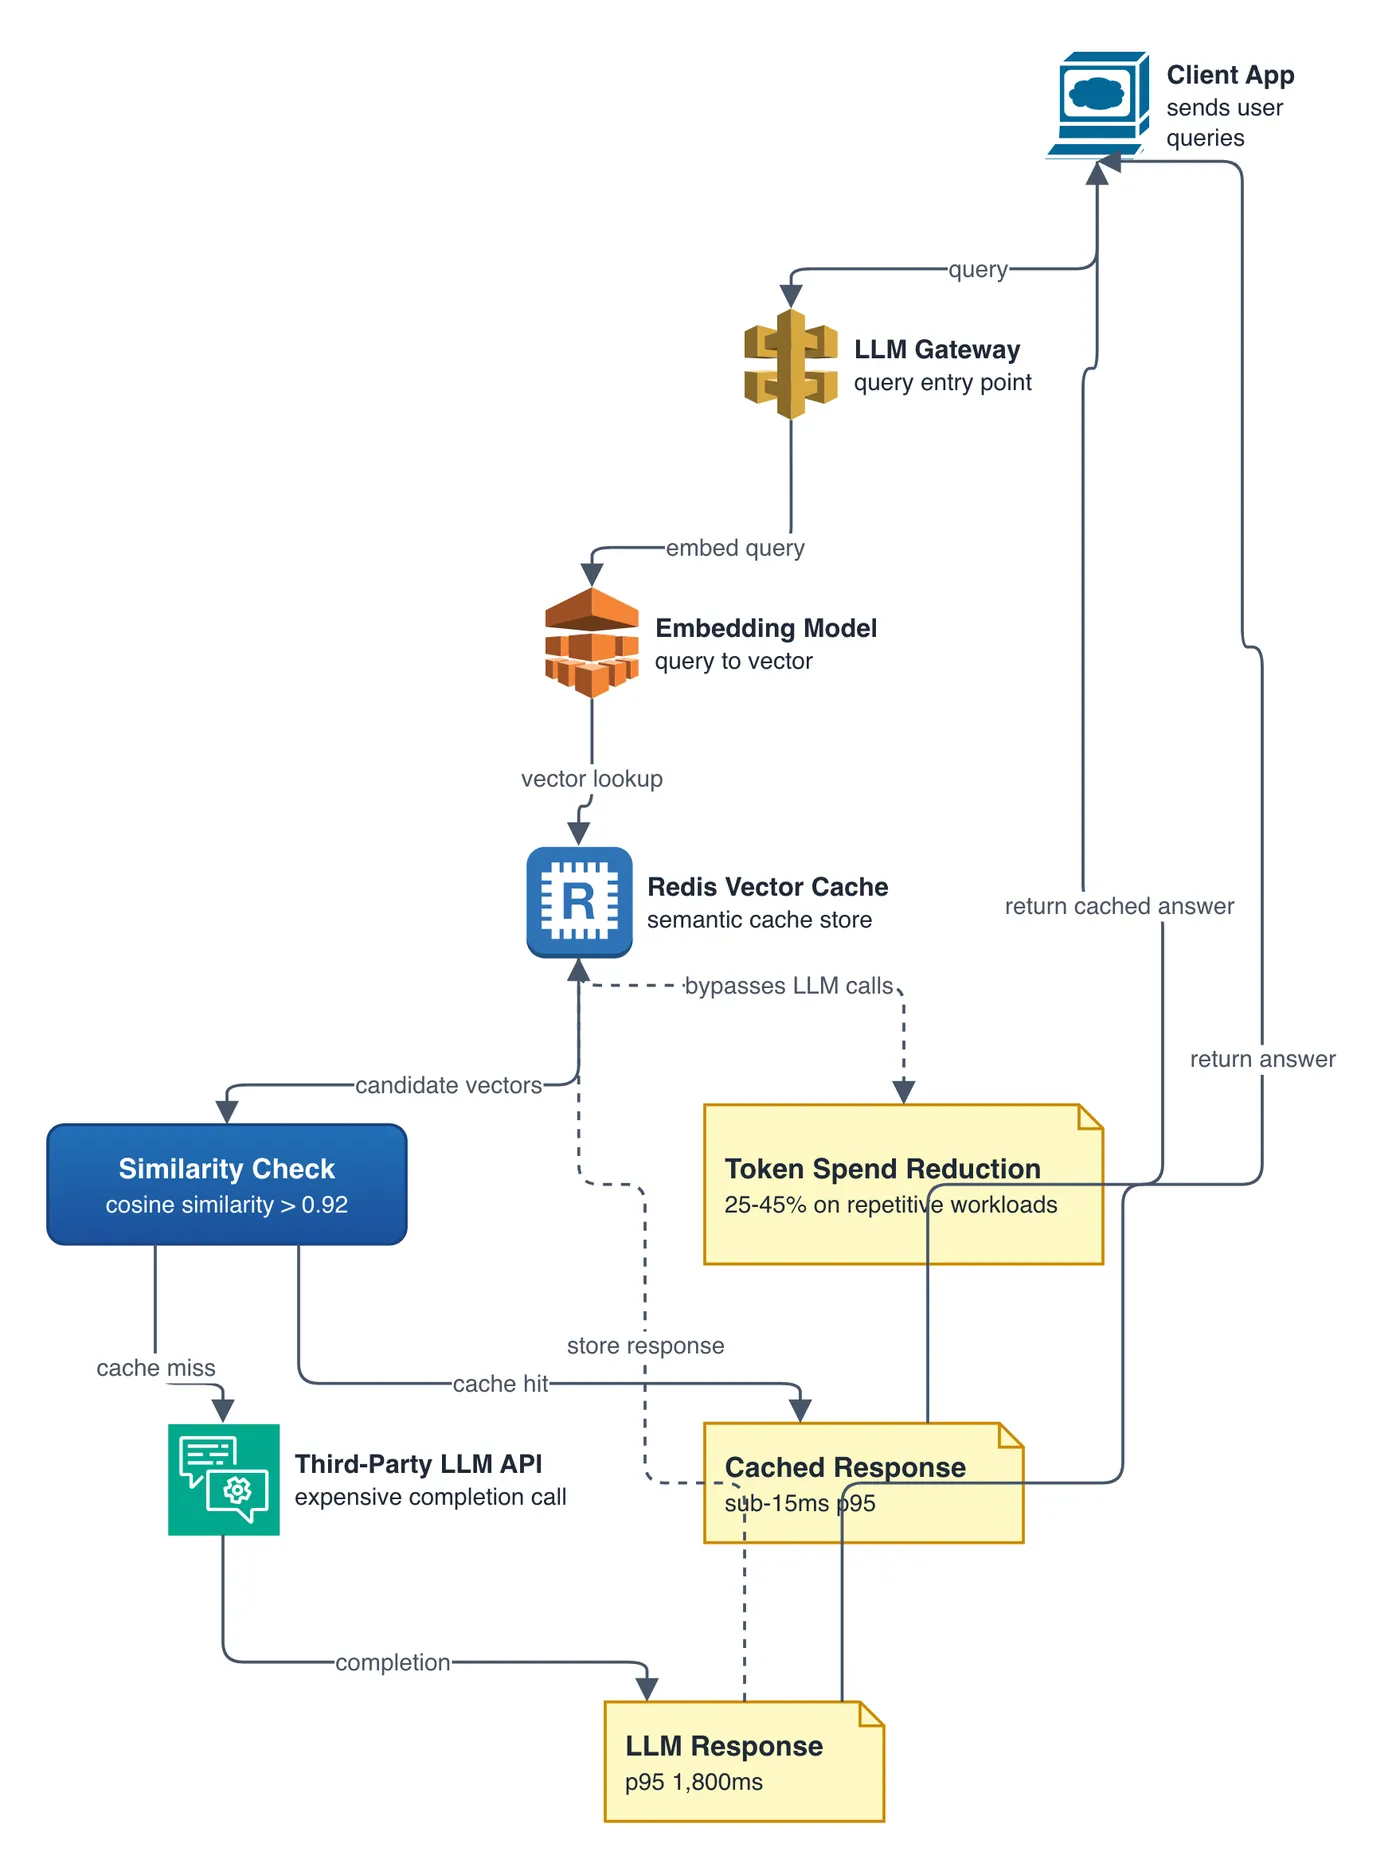
What it shows
- Cosine similarity threshold (>0.92) catches semantic duplicates reliably.
- Drops p95 latency from 1,800ms down to sub-15ms for cached queries.
- Cuts third-party LLM API token spend by 25-45% on repetitive workloads.
The takeaway
Semantic caching turns expensive probabilistic LLM queries into deterministic microsecond key-value lookups.
- #SystemDesign
- #LLMOps
- #Redis
- #MachineLearning
- #SoftwareArchitecture
- #ArtificialIntelligence