LoRA Fine-Tuning Pipeline Explained
Data & AI Pipelines diagram · made in Skemio
What it shows
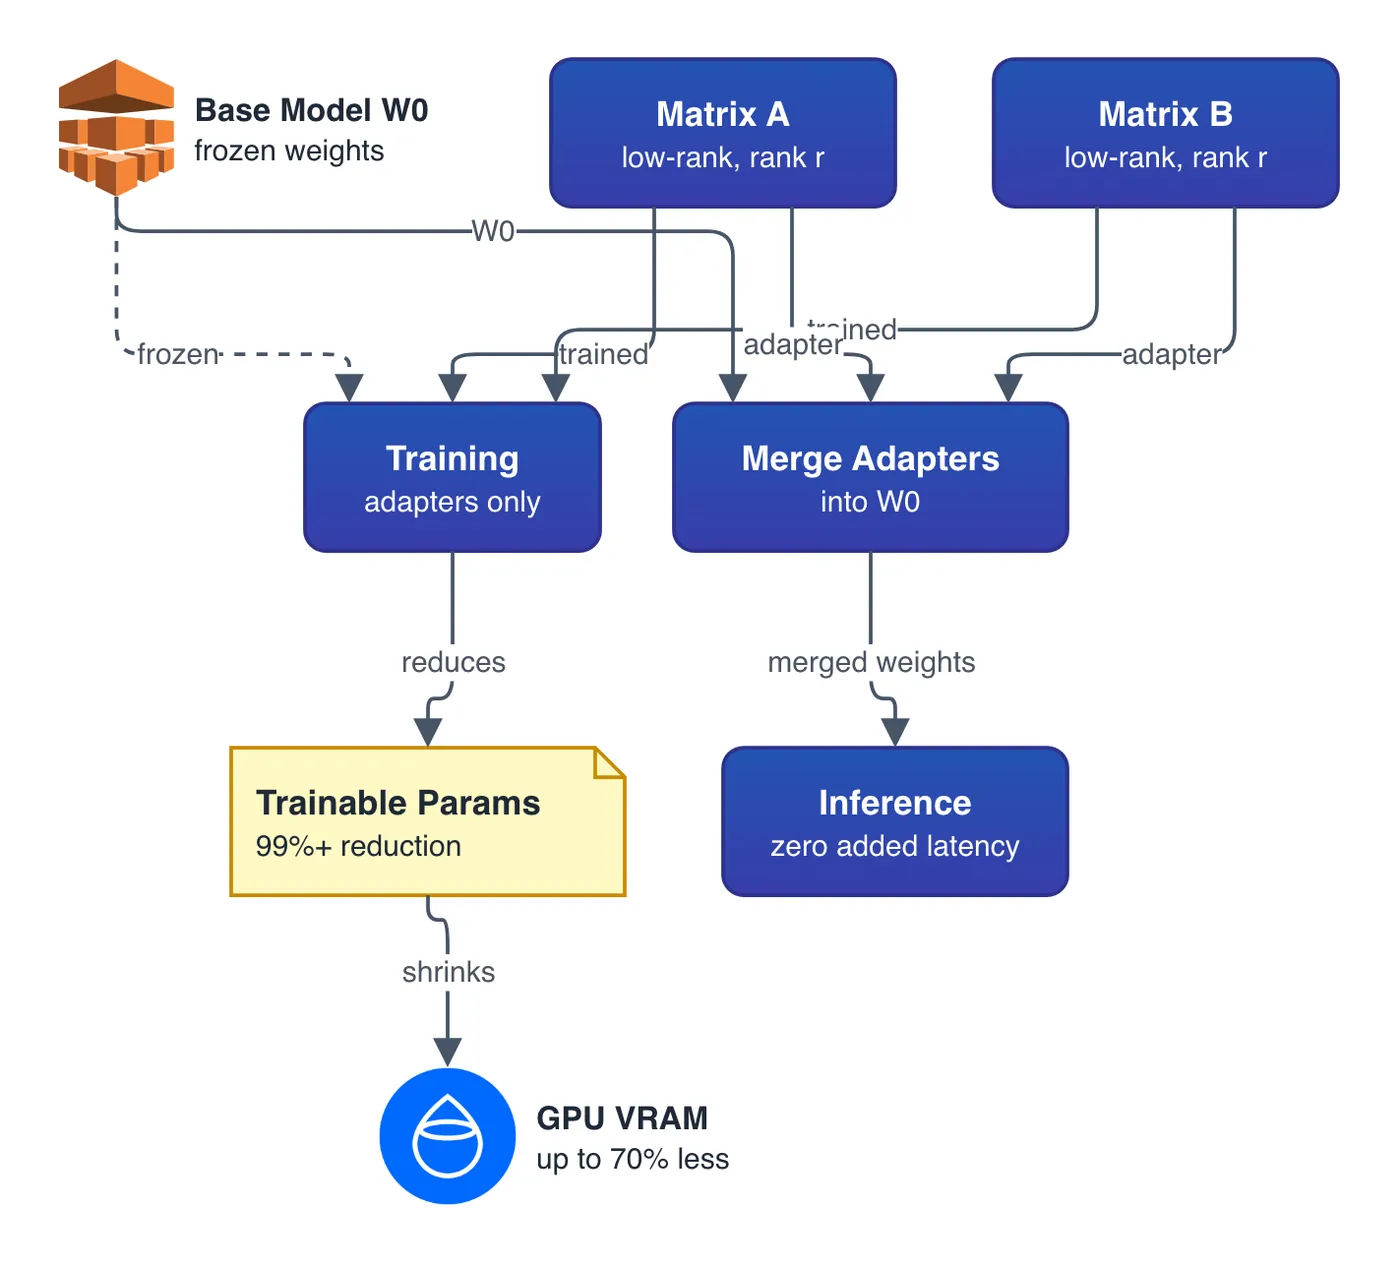
- Freezes base weights W0, adding low-rank matrices A and B (rank r << d).
- Reduces trainable parameters by 99%+, shrinking GPU VRAM usage by up to 70%.
- Merges adapters back into base weights at inference with zero added latency.
The takeaway
LoRA cuts training VRAM dramatically by updating low-rank adapter matrices instead of full model weights.
- #MachineLearning
- #LLMOps
- #DeepLearning
- #LoRA
- #ArtificialIntelligence
- #DataEngineering