Mixture of Experts (MoE) Inference Routing
Data & AI Pipelines diagram · made in Skemio
What it shows
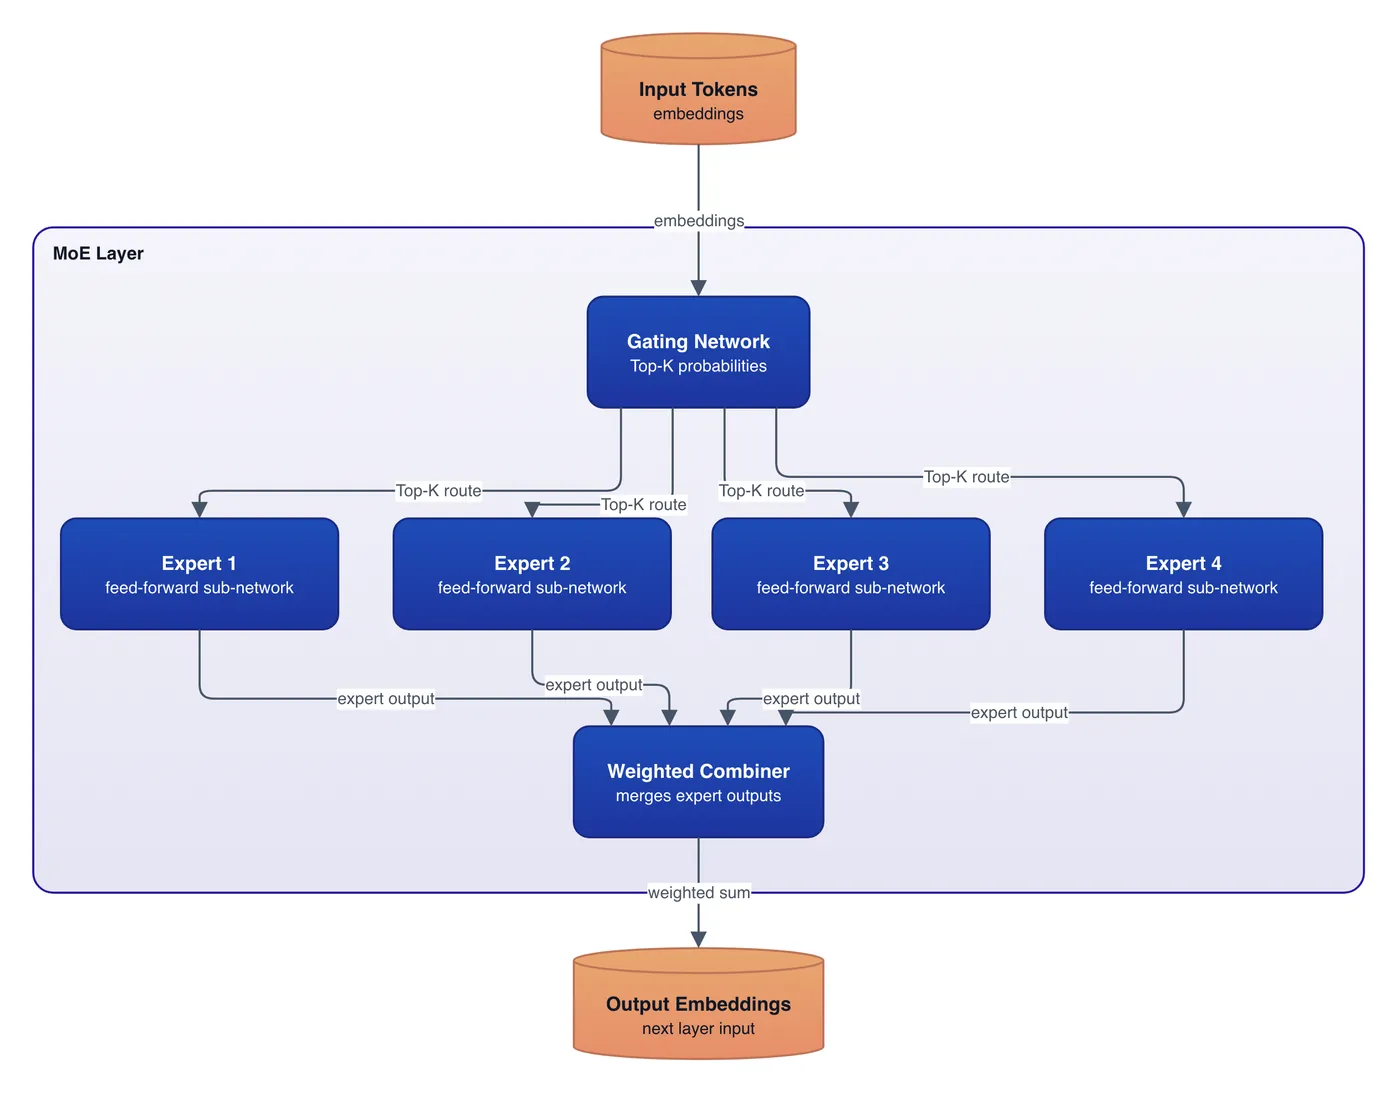
- Gating networks dynamically compute Top-K routing probabilities per token.
- Tokens route only to specialized feed-forward sub-networks (experts).
- A weighted combiner merges expert outputs without dense compute overhead.
The takeaway
MoE expands total parameter capacity while keeping active compute cost per token flat.
- #MixtureOfExperts
- #DeepLearning
- #LLM
- #ArtificialIntelligence
- #MachineLearning