Multi-Modal Embedding Search with CLIP
Data & AI Pipelines diagram · made in Skemio
What it shows
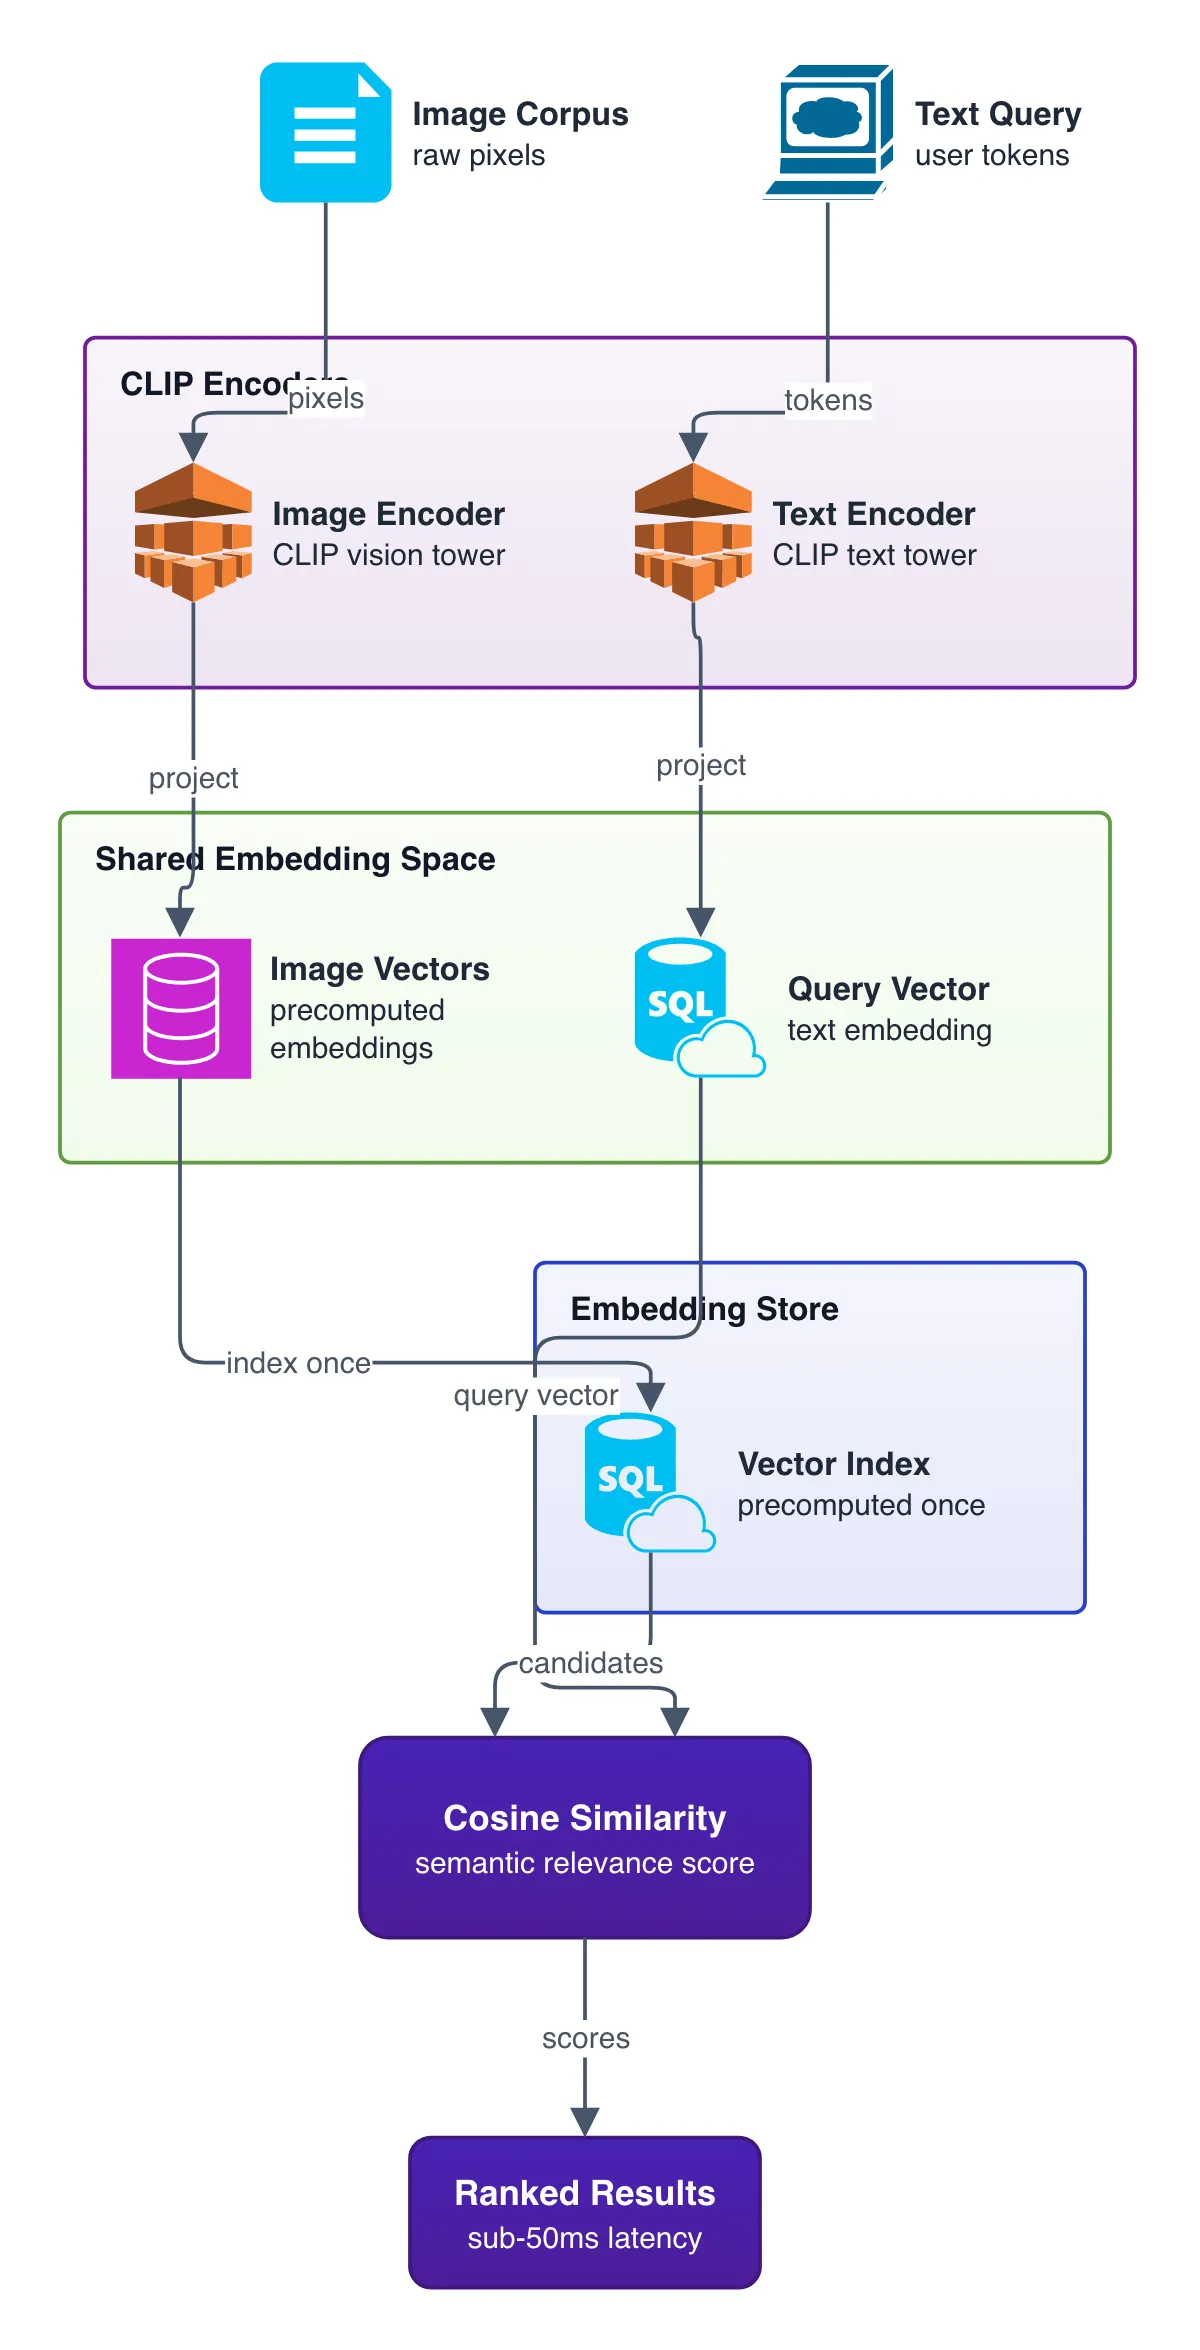
- Contrastive models project text tokens and image pixels into the exact same vector space.
- Cosine similarity directly scores semantic relevance between image and text vectors.
- Image embeddings are precomputed once, keeping query latency sub-50ms.
The takeaway
Shared latent spaces let text queries match image content directly via vector dot products.
- #VectorSearch
- #CLIP
- #ComputerVision
- #MachineLearning
- #AI
- #SystemDesign