Two-Stage Retrieval with Cross-Encoders
Data & AI Pipelines diagram · made in Skemio
What it shows
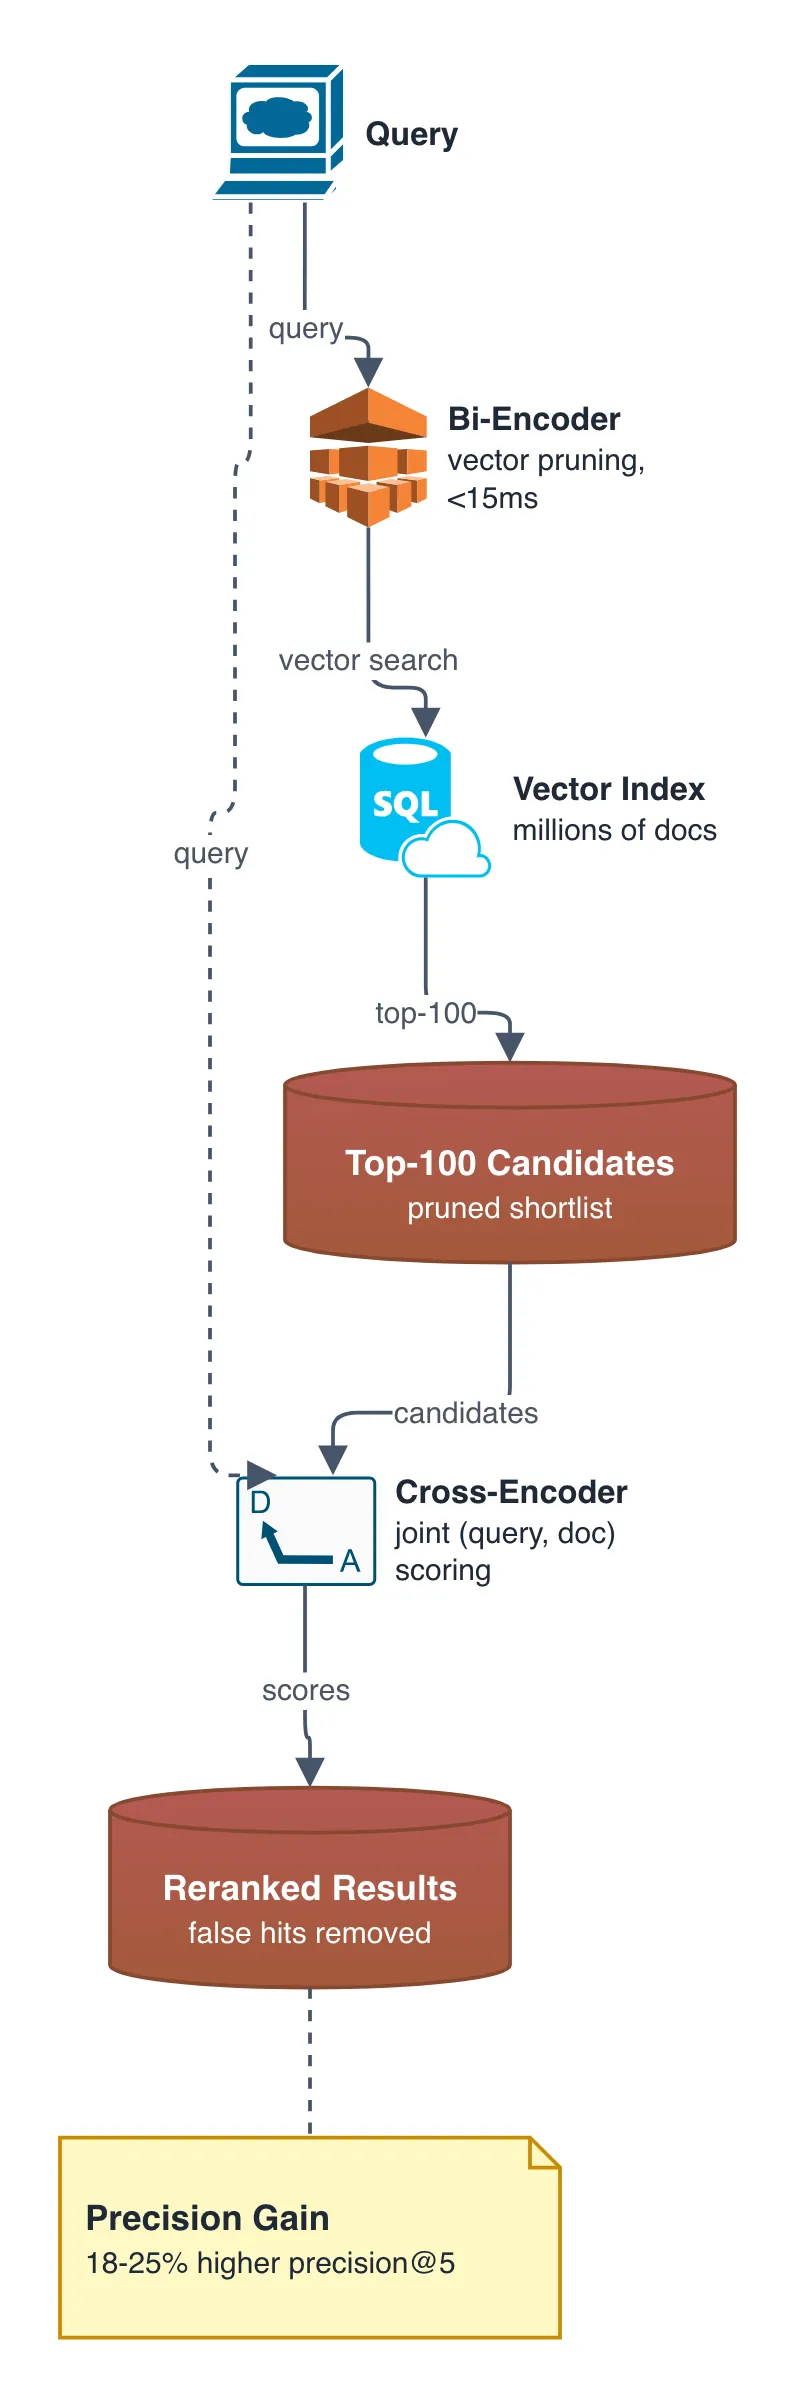
- Bi-encoders prune millions of docs to top-100 candidates in under 15ms.
- Cross-encoders jointly score (query, doc) pairs to eliminate false hits.
- Achieves 18-25% higher precision@5 compared to standalone vector search.
The takeaway
Use fast bi-encoders to cast a wide net, then spend compute on cross-encoders for the top 50.
- #VectorSearch
- #RAG
- #CrossEncoder
- #MachineLearning
- #AIArchitecture
- #GenerativeAI