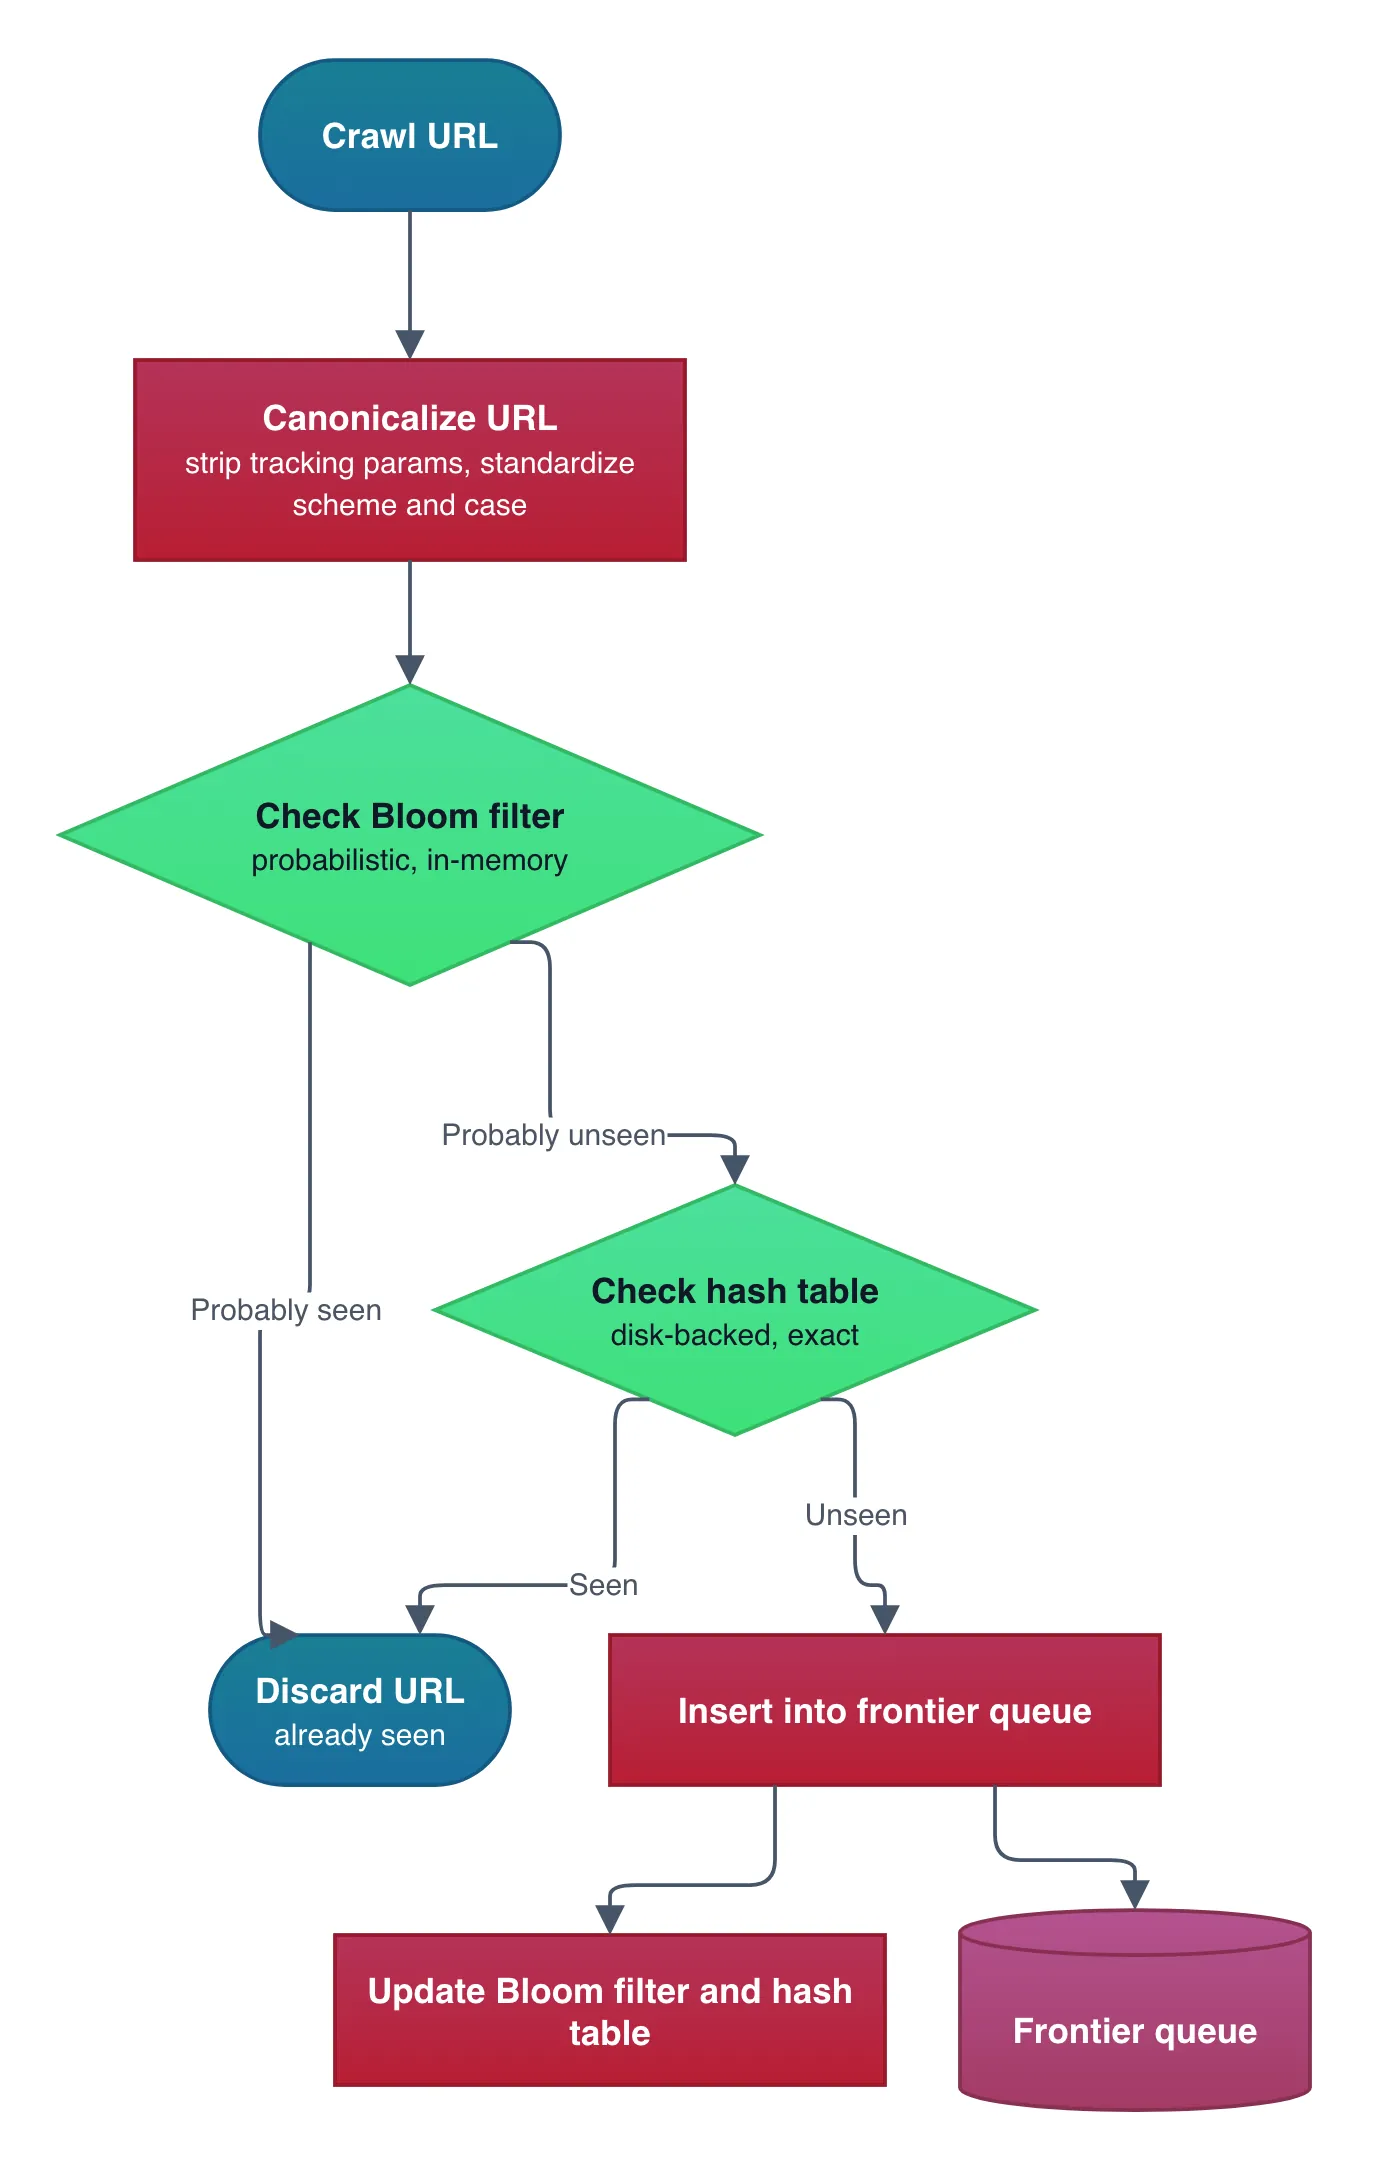
Web Crawler URL Deduplication Flow
Flowcharts & Algorithms diagram · made in Skemio
What it shows
- Canonicalization strips tracking params and standardizes scheme and case.
- Probabilistic Bloom filters filter 99% of unseen URLs in memory.
- Secondary disk-backed hash tables guarantee zero false-positive skips.
The takeaway
Tiering in-memory Bloom filters with persistent hash verification stops crawler duplicates at scale.
- #DataEngineering
- #WebScraping
- #DistributedSystems
- #Algorithms
- #SystemDesign
- #Backend